Imitation learning (IL) teaches language-model agents to reproduce expert actions but not to distinguish them from plausible mistakes. Self-reflection methods expose models to alternatives yet use supervised fine-tuning (SFT) to imitate fixed rationales and actions. We introduce Agentic Critical Training (ACT), which uses reinforcement learning with verifiable rewards (RLVR) to train models to judge actions directly. At each expert-trajectory state, ACT pairs an expert action with an alternative sampled from the initial policy and randomizes their order. The model generates its own reasoning but is rewarded only for selecting the expert action. ACT reuses demonstrations, requires no reference rationales, and allows pair reuse across model sizes. ACT is a warm-up before IL, optionally followed by RL; inference requires no candidate comparison. Across Qwen3-8B and Olmo-3-7B-Instruct on ALFWorld-ID, WebShop, and ScienceWorld, ACT yields average gains of 5.85 points over IL and 4.12 points over IL→RL without ACT, while also improving ALFWorld-OOD. With Olmo on ScienceWorld, the full pipeline gains 15.36 points over CoT prompting and 9.23 points over IL→RL without ACT. Both ACT→IL and the full pipeline outperform supervised reflection baselines. Controls with fixed pairs or matched training durations show that the gains stem from the ACT objective rather than additional data or training. Without reasoning-specific post-training, the standalone ACT checkpoint achieves the highest mean among evaluated models on MATH-500 and GPQA-Diamond, showing that action comparison complements generation.
Motivation
Language-model agents make a sequence of choices while navigating websites, manipulating household environments, conducting scientific experiments, and calling tools. A single plausible but incorrect action can derail the rest of a trajectory. Most agent post-training methods teach the model to generate the demonstrated next action, but do not explicitly teach it to compare that action with plausible alternatives. We study whether adding such a comparison objective can improve agent training.
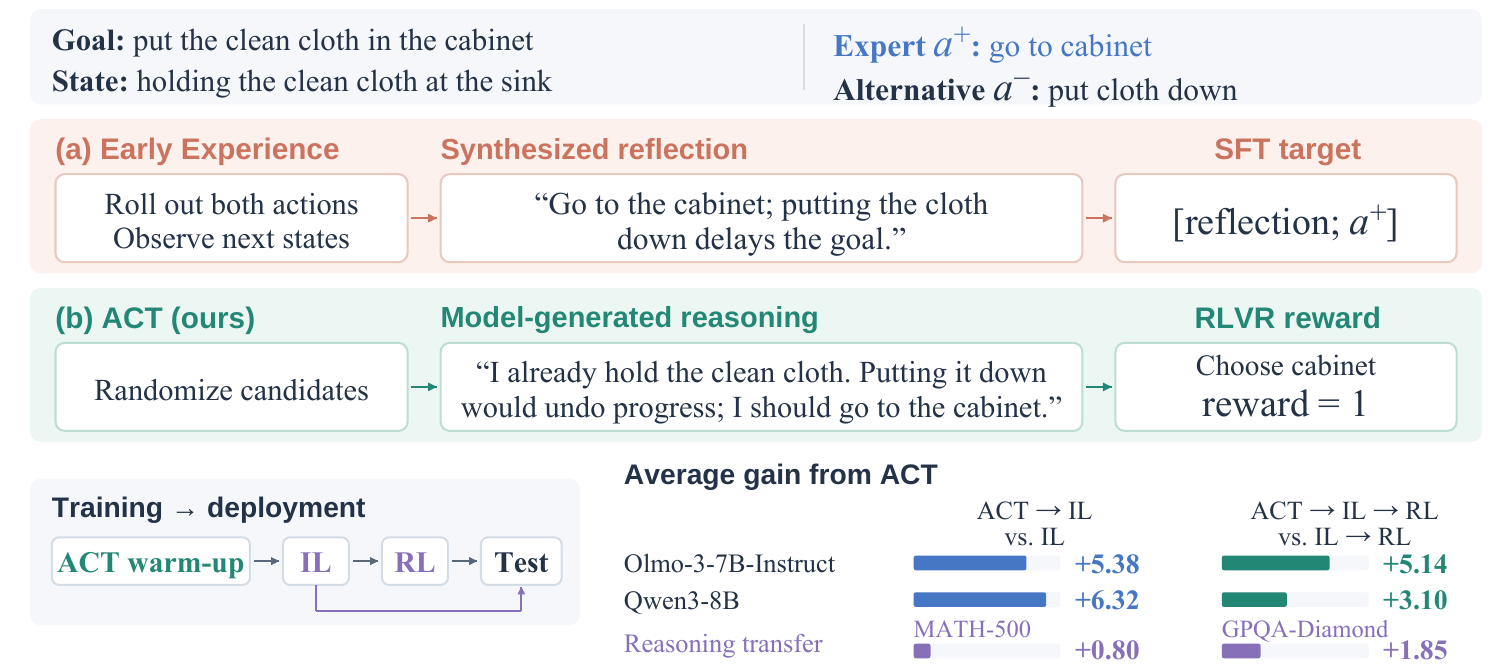
This limitation is clearest in imitation learning (IL). IL maximizes the likelihood of expert actions, so each training example identifies what the agent should do at a given state. It does not show which competing actions should be rejected or what makes them worse. Early Experience adds information about alternatives by rolling out both the expert and alternative actions, observing their resulting next states, and synthesizing a rationale that explains why the expert action is better. Although its targets contain more information than standard behavioral cloning, training still uses next-token prediction to reproduce a fixed rationale and the expert action. The model is given both the explanation and the answer, rather than trained to arrive at the judgment itself, as illustrated in Figure 1(a).
We propose Agentic Critical Training (ACT), shown in Figure 1(b), to train this judgment directly. The model reasons about an expert action and a model-generated alternative, then selects the better one. Reinforcement learning provides a reward based on whether it selects the expert action, without evaluating the chain-of-thought or requiring a match to a reference rationale. The supervision therefore evaluates the decision, while allowing the model to develop its own reasoning for that decision.
Figure 1. (a) Early Experience uses SFT to imitate a synthesized reflection and expert action. (b) ACT trains action judgment through RLVR, verifying the selected action without a reference rationale. ACT precedes IL; optional RL continues from the IL checkpoint. General-reasoning gains are measured at the standalone ACT stage.
The ACT Pipeline
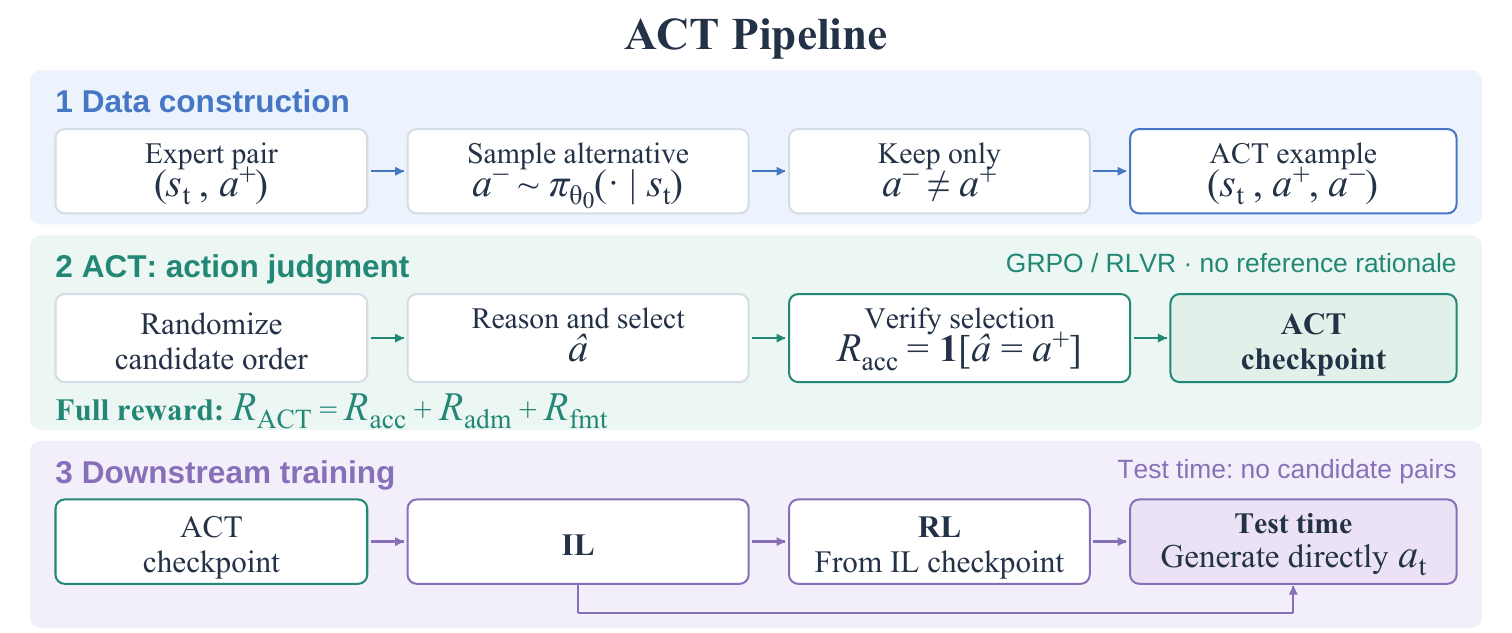
ACT transforms the learning objective from “imitate the expert action” to “identify the better action.” It bridges the pretrained model and downstream policy training by first building the capacity to evaluate actions. The pipeline reuses expert demonstrations to construct action pairs, trains action judgment with Group Relative Policy Optimization (GRPO), and then applies IL with optional RL.
Figure 2. Expert–alternative pairs → ACT checkpoint → IL → optional RL. At test time, the policy generates actions directly, without candidate pairs or comparison.
1 Construct expert–alternative pairs
For each expert state-action pair, we sample an alternative from the initial policy, discard exact matches, and pair the remaining alternative with the expert action. The state includes the task description, recent observation-action history, and current observation. Sampling from the initial policy produces alternatives that reflect its own likely errors. We label the expert action as preferred under the assumption that expert actions are generally better, obtaining labels without reference-rationale generation. Experiments use one sampled alternative per state.
2 Train action judgment with ACT
We randomize candidate order to prevent reliance on a fixed position. Given the task context and candidate pair, the model reasons about which action is better and outputs its choice. GRPO samples multiple responses and trains with a verifiable action-selection reward: its accuracy component checks whether the chosen action matches the expert action. The reward does not evaluate the reasoning content or require a reference rationale, so reasoning is optimized indirectly through correct selection.
3 Continue with IL and optional RL
ACT serves as a warm-up before IL, which trains direct action generation by maximizing the likelihood of expert actions. Optional RL continues from the resulting IL checkpoint. We use ACT stage for the action-judgment warm-up, full ACT pipeline for ACT → IL → RL, and IL → RL w/o ACT for the corresponding baseline.
ACT is a training stage, not an inference-time reranking procedure. At test time, the policy generates the next action directly, without first generating and comparing multiple candidates.
Main Results
We evaluate Qwen3-8B and Olmo-3-7B-Instruct on ALFWorld, WebShop, and ScienceWorld, using the same expert trajectories across training-based methods. Adding ACT improves both IL and IL → RL, including on ALFWorld-OOD. The full ACT pipeline achieves the highest mean in all four evaluation settings for both backbones; ACT → IL also outperforms Early Experience, SAND, and Agent-R in every setting. Comparisons using the same expert and alternative actions suggest that rewarding a correct judgment is more effective than imitating a fixed rationale.
Table 1 · Qwen3-8B
Method
ALFWorld ID
ALFWorld OOD
WebShop
ScienceWorld
Prompt w/o CoT thinking
32.62±2.63
24.88±2.88
18.20±0.85
16.99±2.85
Prompt w/ CoT thinking
50.00±4.77
39.30±7.72
15.53±0.34
18.68±0.34
ACT stage
62.14±7.72
59.45±9.23
21.53±4.58
30.04±2.13
Imitation Learning (IL)
85.71±0.58
79.85±2.79
28.00±1.31
21.94±2.65
Early Experience
86.43±1.55
79.10±10.57
30.93±1.23
22.82±1.30
SAND
85.71±1.16
83.09±0.93
20.27±1.36
29.41±0.46
Agent-R
87.86±1.17
81.09±0.93
24.07±4.20
16.95±1.79
ACT → IL
89.76±1.88
83.58±3.80
32.00±1.18
32.85±0.15
IL → RL w/o ACT
94.28±1.54
90.80±0.70
39.53±1.06
30.52±0.46
Full ACT pipeline
96.19±0.67
91.54±0.35
42.80±0.59
34.63±0.33
Table 2 · Olmo-3-7B-Instruct
Method
ALFWorld ID
ALFWorld OOD
WebShop
ScienceWorld
Prompt w/o CoT thinking
0.71±0.58
0.25±0.35
11.47±0.34
3.47±2.04
Prompt w/ CoT thinking
11.91±0.67
10.94±2.14
12.47±0.47
6.31±3.97
ACT stage
16.90±1.69
11.94±3.71
11.53±1.31
12.03±0.92
Imitation Learning (IL)
62.62±3.37
56.97±9.33
12.87±9.02
8.10±0.19
Early Experience
42.62±3.51
35.32±6.40
13.27±7.04
8.97±0.71
SAND
36.91±1.78
28.11±3.52
7.00±0.33
8.11±0.31
Agent-R
66.43±4.67
63.93±4.93
13.40±0.86
9.25±0.70
ACT → IL
74.52±2.21
67.41±4.06
14.80±7.27
10.40±0.89
IL → RL w/o ACT
81.67±2.21
77.11±5.91
23.40±1.23
12.44±1.54
Full ACT pipeline
87.14±3.08
83.83±0.35
24.13±0.41
21.67±0.61
Metrics: ALFWorld and WebShop report success rate (%); ScienceWorld reports mean episode score (0–100). Values are mean ± standard deviation over three runs; bold denotes the highest mean.
Stronger downstream training
ACT adds 6.32 / 3.10 points to IL / IL → RL on Qwen3, and 5.38 / 5.14 points on Olmo, averaged over the three ID benchmarks. On Olmo ScienceWorld, the full pipeline gains 9.23 points over IL → RL and 15.36 over CoT prompting.
Generalization across tasks and model sizes
On ALFWorld-OOD, ACT improves IL from 79.85 → 83.58 on Qwen3 and 56.97 → 67.41 on Olmo. Adding ACT to IL → RL also improves OOD performance on both backbones. Pairs collected from Qwen3-8B also effectively train Qwen3-4B without re-collection or adaptation, allowing collection costs to be shared across model sizes.
Analysis
Training objective and continuation controls
We compare ACT with alternative objectives on the same action pairs, and with additional IL or RL training at matched total epochs. The controls show that ACT’s gains are not explained by different data or additional training alone.
Table 3a · Matched IL continuation
Method
ALFWorld ID
ALFWorld OOD
WebShop
ScienceWorld
Imitation Learning (IL)
85.71±0.58
79.85±2.79
28.00±1.31
21.94±2.65
IL → IL
84.76±0.89
79.11±3.71
31.40±2.57
22.01±2.01
ACT → IL
89.76±1.88
83.58±3.80
32.00±1.18
32.85±0.15
Table 3b · ACT-stage objective and matched RL controls
Method
ALFWorld ID
ALFWorld OOD
WebShop
ScienceWorld
IL → RL w/o ACT
94.28±1.54
90.80±0.70
39.53±1.06
30.52±0.46
IL → RL → RL
90.00±2.10
89.80±3.47
33.40±3.82
20.14±1.09
Full pipeline (SFT-on-choice)
94.76±1.34
92.78±1.41
37.73±1.48
30.10±0.19
Full pipeline (DPO)
93.57±0.58
90.05±1.53
41.40±0.99
33.56±0.27
Full pipeline (no-reasoning)
94.52±0.67
92.54±0.61
38.47±2.51
28.12±2.33
Full ACT pipeline
96.19±0.67
91.54±0.35
42.80±0.59
34.63±0.33
Mean ± standard deviation across three runs. Continuation comparisons match six total epochs for IL → IL and ACT → IL, and nine for IL → RL → RL and the full ACT pipeline.
ACT leads on ALFWorld-ID, WebShop, and ScienceWorld in the objective controls. SFT-on-choice leads on ALFWorld-OOD (92.78). Extending IL or RL alone does not reproduce the gains from action judgment.
Causal rationale intervention
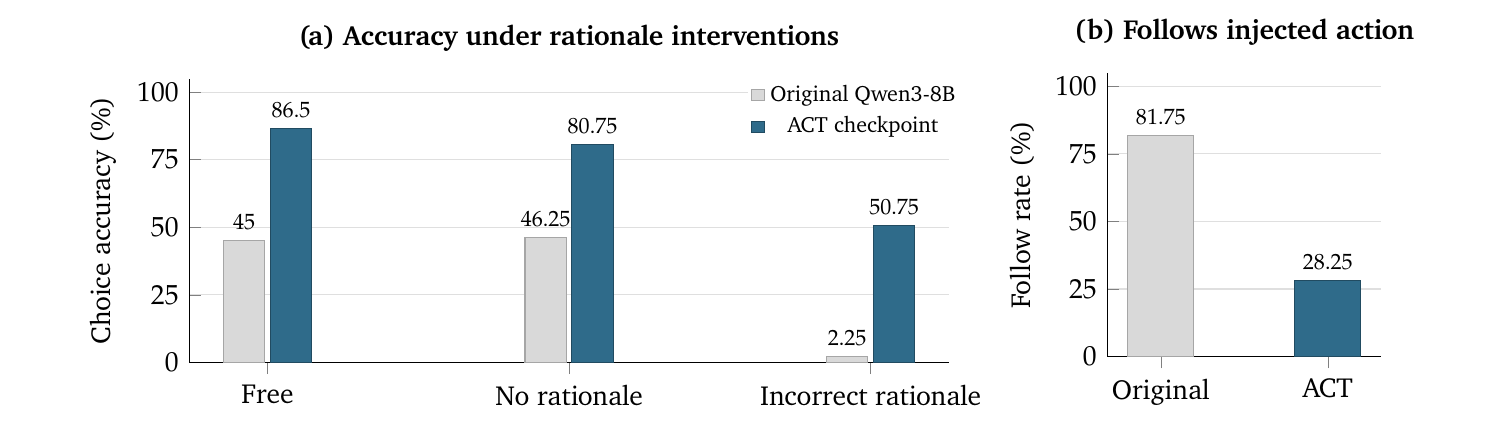
Interventions on 400 held-out ALFWorld action pairs compare the original Qwen3-8B model with the standalone ACT checkpoint. Removing ACT’s rationale lowers choice accuracy from 86.50% to 80.75%; injecting an incorrect rationale lowers it to 50.75%, versus 2.25% for the original model. These results indicate that ACT’s reasoning is behaviorally relevant to its action selection, and that the trained checkpoint is more resistant to misleading rationales.
Figure 3. ACT’s reasoning is behaviorally relevant to action selection. Under an incorrect rationale, the rate of following the injected action drops from 81.75% for the original model to 28.25% for ACT.
Generalization to General Reasoning
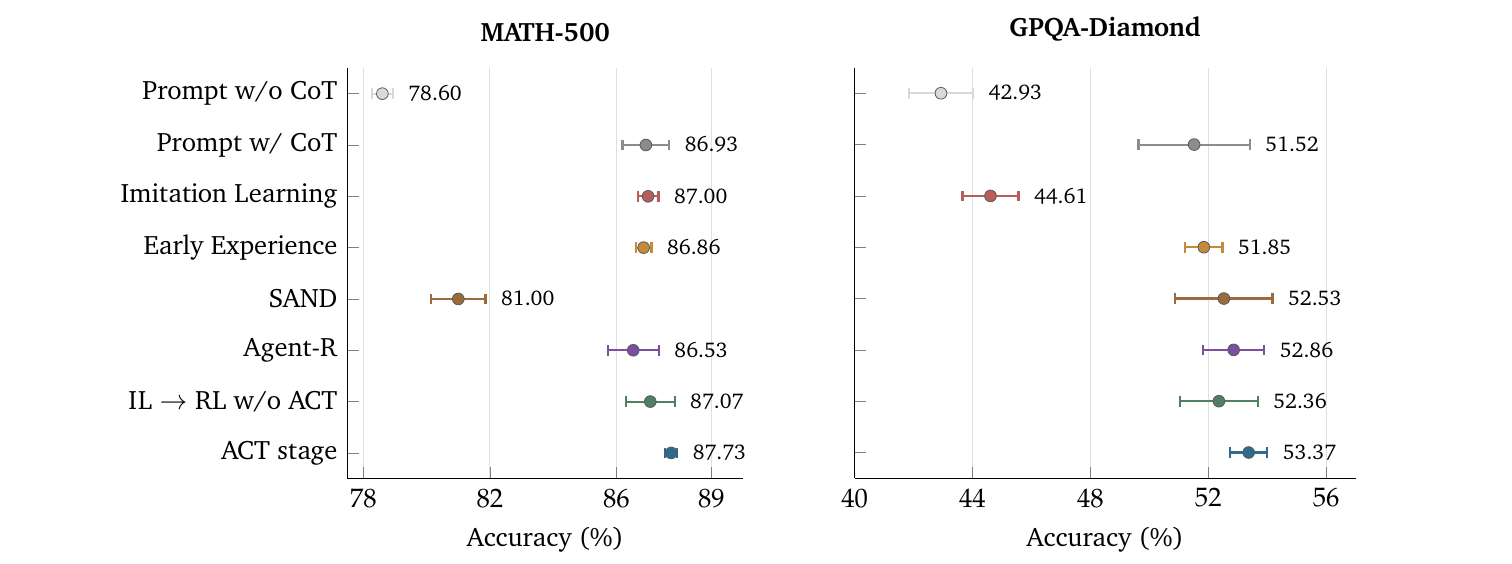
After training only on ALFWorld agent data, the standalone ACT-stage checkpoint attains the highest mean among evaluated models on MATH-500 and GPQA-Diamond. These checkpoints receive no mathematical or scientific reasoning data during post-training.
Figure 4. Standalone ACT reaches 87.73% on MATH-500 and 53.37% on GPQA-Diamond: +0.80 and +1.85 points over CoT prompting. Points and error bars show mean ± standard deviation over three runs. These results refer to ACT before downstream IL or RL.
Reference
If you find our work useful, please cite our paper:
@article{liu2026agentic,
  title={Agentic Critical Training},
  author={Liu, Weize and Liu, Minghui and Ho, Sy-Tuyen and Lee, Yongkyun and
          Schoen, Andrew Adams and Chakraborty, Souradip and Wang, Xiyao and Huang, Furong},
  journal={arXiv preprint arXiv:2603.08706},
  year={2026}
}